
On this page
On November 18, 2026, creative marketplace Contra Labs and evaluation infrastructure provider BenchFlow introduced the Frontier Design Benchmark. Among 17 initial entrants (16 AI models plus a human designer reference baseline), an unannounced stealth model named Gestalt claimed the top spot—reaching 1931 Elo with a 90% win rate on the November 19 live leaderboard and becoming the first model rated above human golden designs (1739 Elo).
Leaderboard Standings & The 204-Elo Separation Between Tiers
**Reconciling the Launch Post Snapshot and Live Leaderboard: **In the November 18 announcement post snapshot, Gestalt was reported at 1,928 Elo (89% win rate, 378 of 423 votes) ahead of Claude Fable 5.2 at 1,714 Elo; by November 19 on the live leaderboard (4,311 total blind votes), Gestalt stood at 1931 Elo (90% win rate, 95% CI 86%–92%, 420 votes), followed by Human golden at 1739 Elo (74% win rate, 95% CI 71%–78%, 571 votes). Gestalt's 95% confidence interval does not overlap with the human baseline, and designers picked Gestalt 20 out of 28 times in direct head-to-head comparisons.
**Top Six Public Models vs. Lower Nine Models: **Six public models cluster between 1638 and 1713 Elo: Claude Fable 5.2 (1713 Elo, from $127.22/site), Claude Opus 5.5 (1691 Elo, $24.26/site), GPT-6.1 Sol (1668 Elo, $1.31/site), Claude Sonnet 5.5 (1667 Elo, $20.49/site), Moonshot AI's Kimi K3.1 Pro (1663 Elo, $1.91/site), and GPT-6 Astra (1638 Elo, $7.33/site). A 204-Elo gap separates them from the remaining nine models (1121 to 1434 Elo, spanning Qwen3.8 Max down to DeepSeek V4 Pro).
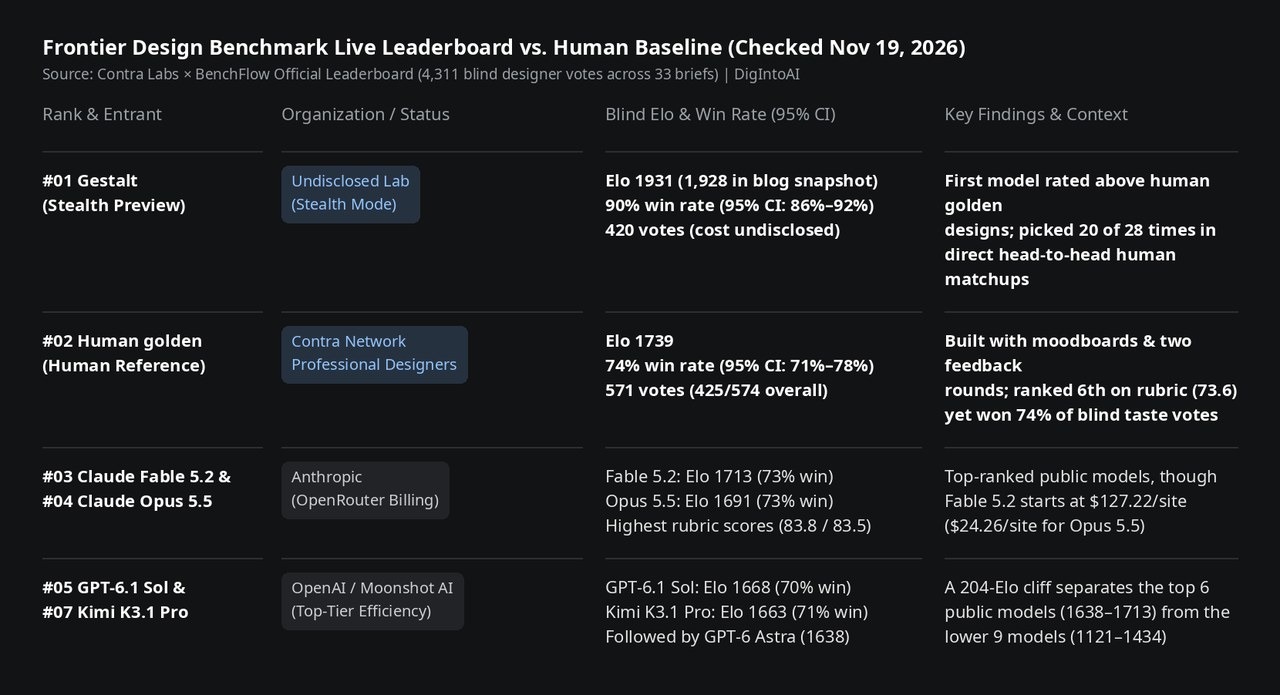
Image source: compiled by DigIntoAI from the official Contra Labs × BenchFlow leaderboard.
Real Client Briefs, Rubric vs. Taste, and AI Slop Patterns
**33 Production Briefs & Native Lab Harnesses: **Drawn from 27 rewritten Contra marketplace jobs and 6 startup partner projects (19 with client logos, 17 requiring mobile responsiveness), the benchmark tests multi-page marketing sites, checkout flows, online courses, and mobile apps. BenchFlow runs models via OpenRouter inside each lab's native agent harness wherever possible, meaning scores reflect the combined model-plus-harness workflow.
**Where Automated Rubrics & Human Taste Diverge: **Alongside blind votes from 35 practicing designers (8-year median experience; the homepage hero cites 68 network designers), submissions are scored on a 34/35-item Design Rubric and a 0–100 AI Slop Detector. While model rubric scores correlate with Elo at r = 0.94, Human golden scored 73.6 (sixth overall) due to minor execution flaws like low button contrast—yet still won 74% (425 of 574) of blind human votes because rubrics catch mistakes rather than aesthetic taste. On the AI Slop Detector, Human golden reads 0.9 and Gestalt reads 1.2 (avoiding common AI tropes such as tiny uppercase section labels, italicized headline words, 01/02/03 numbered sections, and pervasive bordered cards), whereas Claude (31–38), GPT (41–53), and Gemini (54–57) score substantially higher.
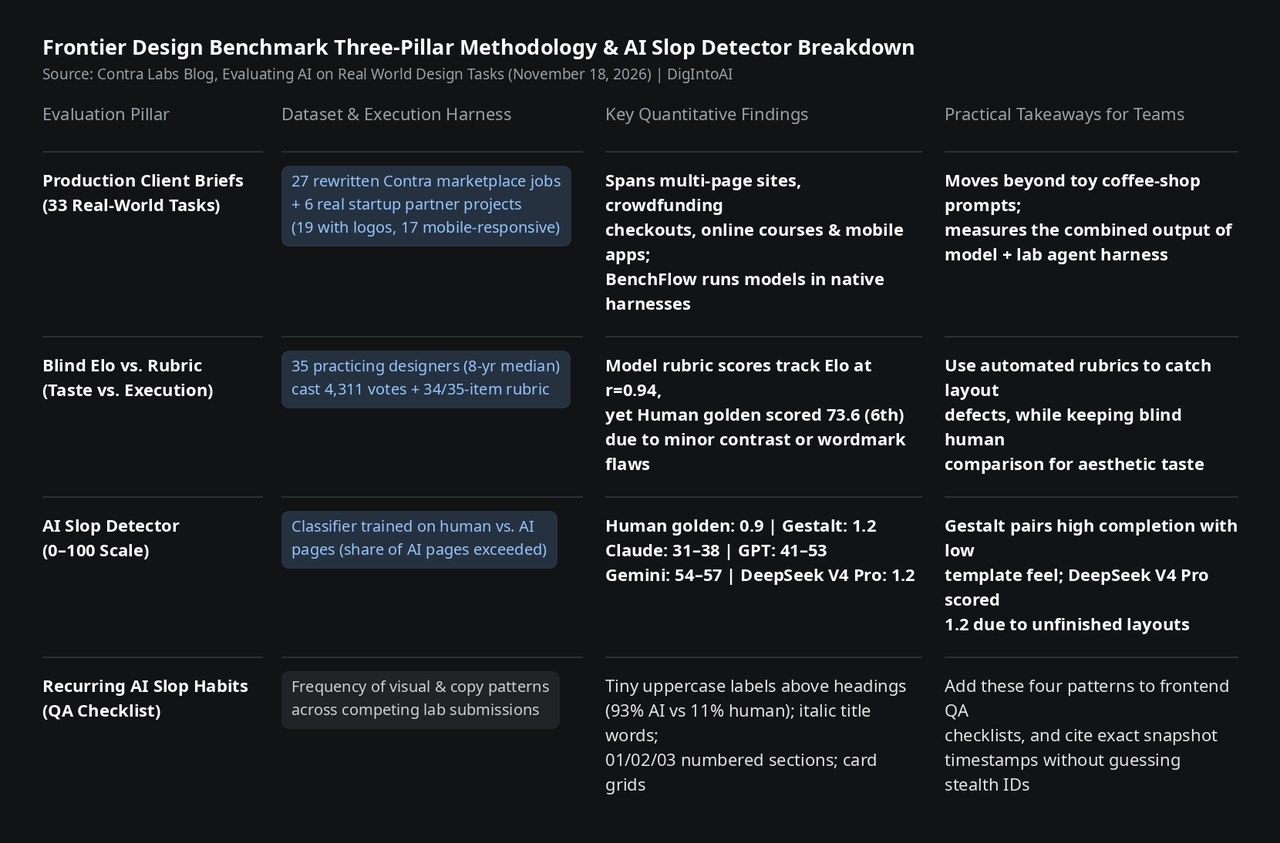
Image source: compiled by DigIntoAI from Contra Labs' official methodology and blog analysis.
Factual Boundaries Around Gestalt's Identity
**Stealth Status & Scope Limits: **Contra Labs and BenchFlow describe Gestalt strictly as a high-quality design model currently in stealth, with no developer identity, parameter count, per-site cost, or public release date disclosed. Readers should treat the rankings as a specialized commercial web and UI design benchmark (combining model and lab harness) rather than a general-purpose leaderboard, and avoid attributing Gestalt to any unconfirmed lab until officially announced.