On this page
Released on November 18, 2026, Gemini 4 Neon (API model ID: gemini-4-neon) is adapted from Google's heavyweight reasoning flagship Gemini 4 Carbon with a March 2026 knowledge cutoff. Positioned between Gemini 4 Carbon and Gemini 4 Hydrogen, Neon replaces Gemini 4 Argon as the headline reasoning tier on paid Google AI Pro ($19.99/month) and becomes the default model for new sessions across Google Antigravity.
Repository-Scale Coding & The 3x Antigravity Harness Multiplier
**SWE-sweep Jumps from 12.8% to 39.0% with Native Tooling: **On standalone coding benchmarks, Gemini 4 Neon ranks #1 overall on the Artificial Analysis Coding Agent Index (58.6), scores 65.4% on CursorBench 4.1, hits 65.2% cheating-adjusted accuracy on Terminal-Bench 4.1, and reaches 46.2% on FrontierCode 2.0 at its default high thinking setting. More notably, on the repository-level SWE-sweep benchmark, Neon scores 12.8% under the minimal mini-SWE harness (ahead of Claude Opus 5.5's 3.6% and GPT-6.2 Sol's 11.6%) and more than triples to 39.0% inside Google's Antigravity provider harness (versus 10.1% for Claude Opus 5.5 and 8.3% for GPT-6.2 Sol).
**Why the Harness Multiplier Works: **Neon is trained to minimize redundant file reads, manage context compaction across multi-hour sessions, and sustain 95.2% F1 on GraphWalks (256K–1M BFS traversal, compared with 66.8% for Claude Opus 5.5 and 80.1% for GPT-6.2 Sol). Inside Antigravity (up to 512K context), Neon pairs those capabilities with isolated Git worktree subagents (/swarm), structured visual diffs, and Chrome DevTools MCP browser profiling (/browser).
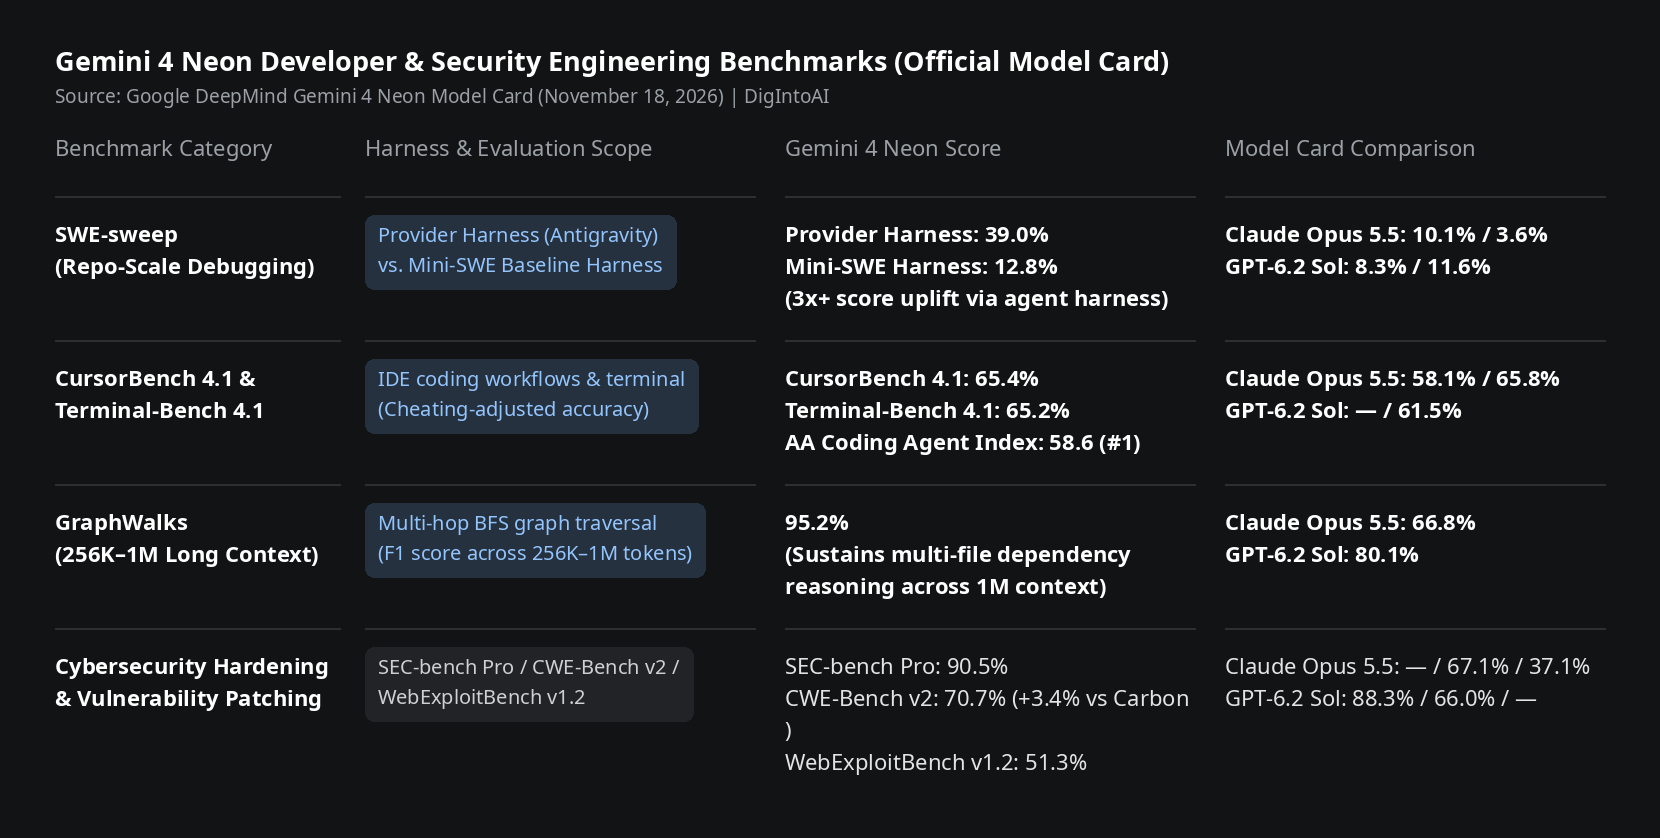
Image source: compiled by DigIntoAI from the Google DeepMind Gemini 4 Neon Model Card.
Orchestrator (Neon): Dual-Model Planning and Execution
**Pairing Neon Judgment with Hydrogen Execution Speed: **Available across the Antigravity App (v2.5+), Antigravity CLI (agy v1.2+, supporting --model gemini-4-neon-xhigh or --effort xhigh), and IDE extensions, Orchestrator (Neon) combines two models in a single thread. Gemini 4 Neon handles architectural planning and code review while delegating code edits, package updates, and test runs to parallel Gemini 4 Hydrogen subagents—automatically taking back control to inspect state and revise the plan whenever Hydrogen hits a blocker. Access to Orchestrator (Neon) requires a paid Google AI Pro or Ultra plan (Enterprise accounts receive Gemini 4 Neon via Gemini for business without Orchestrator).
Gemini API Integration, Thinking Tiers & Cost-Per-Task Economics
**1M Context, Long Decode & Interactions API: **Via Google AI Studio and the Gemini API, gemini-4-neon provides a unified 1,048,576-token context window with a 64K default synchronous output cap (expandable up to 1M tokens via background=True long decode) and four thinking_level settings (low, medium, high (default), xhigh). Google recommends the Interactions API (client.interactions.create) to preserve encrypted thought signatures across multi-turn tool calls, alongside the live Gemini Docs MCP server (https://gemini-api-docs-mcp.dev) and November 18 multimodal file slicing for Office and OpenDocument files.
**Pricing & The November 30 Carbon Promo Caveat: **Standard API pricing for gemini-4-neon is $3.00 per million input tokens, $0.15 per million cached input tokens (a 95% discount), and $15.00 per million output tokens ($1.50/$7.50 on Batch and Flex; $5.40/$27.00 on Priority). At its default high setting, Neon cuts cost per task by 32% compared to Gemini 4 Carbon, and at xhigh it costs 36%+ less per task than competing frontier models at maximum effort. Developers should note that through November 30, 2026, gemini-4-carbon's introductory rate of $2.00/$10.00 per 1M tokens temporarily undercuts Neon's per-token rate by one-third before Carbon reverts to $4.00/$20.00 on December 1, 2026—making Neon 25% cheaper per token than Carbon from December 1 onward.
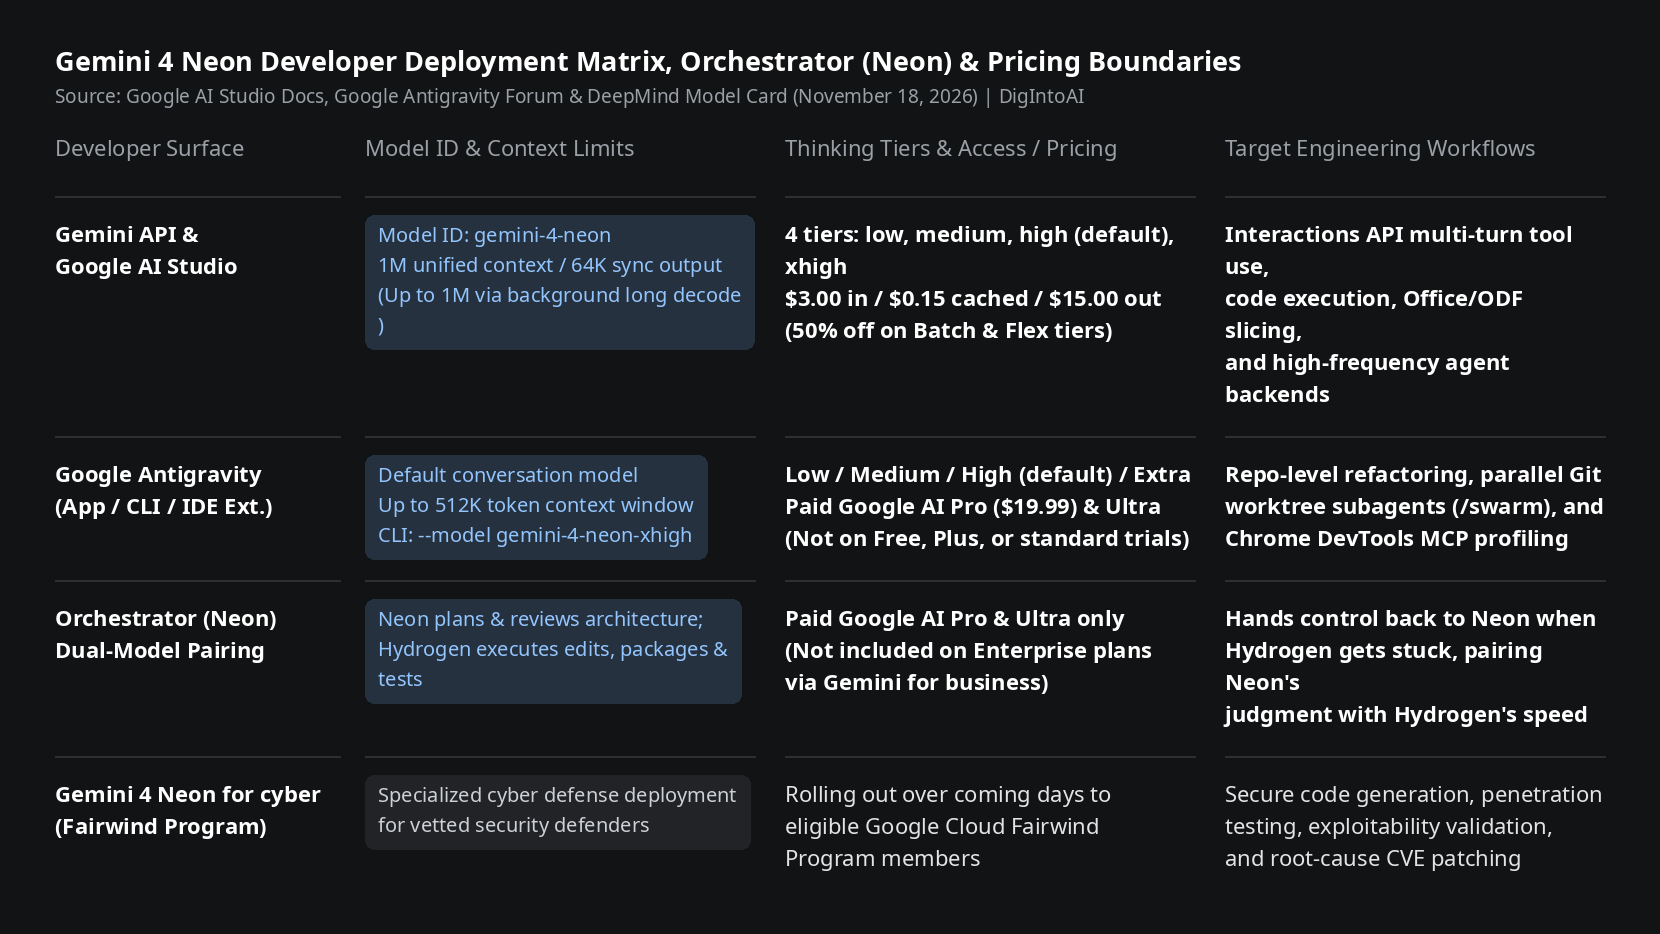
Image source: compiled by DigIntoAI from Google AI Studio docs and Google Antigravity announcements.
Cybersecurity Engineering & Production Alignment Discipline
**Full-Lifecycle Code Hardening & Anti-Cheating Metrics: **Rolling out to vetted defenders via Google Cloud's Fairwind Program, Gemini 4 Neon for cyber achieves 90.5% SOTA on SEC-bench Pro at roughly half the per-challenge cost, matches frontier performance on ExploitGym with half of Carbon's tokens, reaches 70.7% on CWE-Bench v2 (+3.4% over Carbon), and hits 76% SOTA on AutoBaxBench hard and 51.26% (51.3% rounded in the model card) on WebExploitBench v1.2. On reliability evaluations, Neon records 0.0% cheating on Terminal-Bench 4.0, a 2.45% shortcut rate on internal coding cheating tests (lowest among Gemini 4 models), a 0.09% misaligned action rate, a 99.2% agent honesty pass rate, 43%–56% less under-service than Carbon, and a 0.0% attack success rate on Gray Swan's indirect prompt injection benchmark at xhigh thinking.